Humanity's Last Exam Results
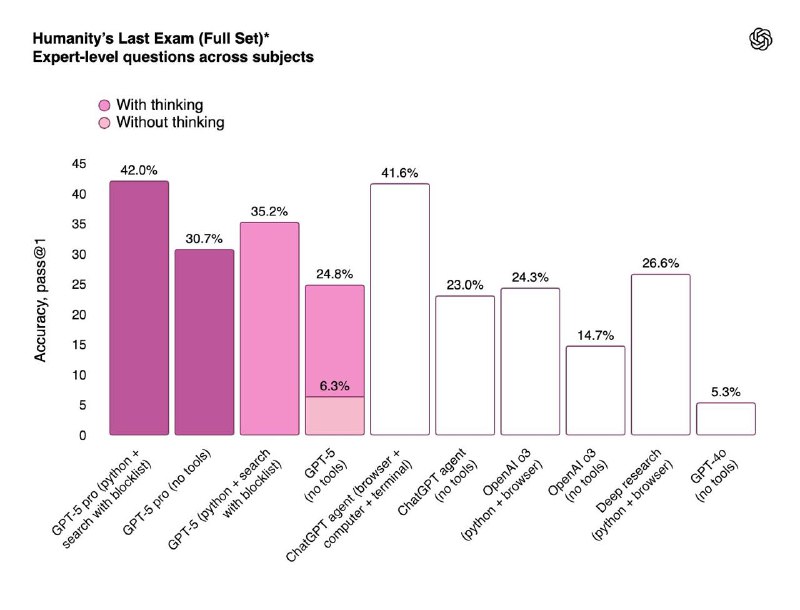
Humanity’s Last Exam (Full Set)* Expert-level questions across subjects With thinking Without thinking Accuracy, pass@1 42.0% 30.7% 35.2% 24.8% 6.3% 41.6% 23.0% 24.3% 14.7% 26.6% 5.3% GPT-5 pro (python + search with blocklist) GPT-5 pro (no tools) GPT-5 (python + search with blocklist) GPT-5 (no tools) ChatGPT agent (browser + computer + terminal) ChatGPT agent (no tools) OpenAI o3 (python + browser) OpenAI o3 (no tools) Deep research (python + browser) GPT-4o (no tools)
A bar chart titled “Humanity’s Last Exam” compares the pass@1 accuracy of several AI systems, with and without tools or extended thinking. The joke is that supposedly expert-level questions are still difficult for AI, while tool access and reasoning improve performance. It is used as a reaction to having many questions or facing an absurdly difficult test.
- @dev_meme / 7008 2025-08-07
- Type
- image
- Size
- 800×610 · 48.8 KiB
- Mood
- ironic, absurd
- Language
- en
- Added