Google AI Dataset Goes Horribly Wrong
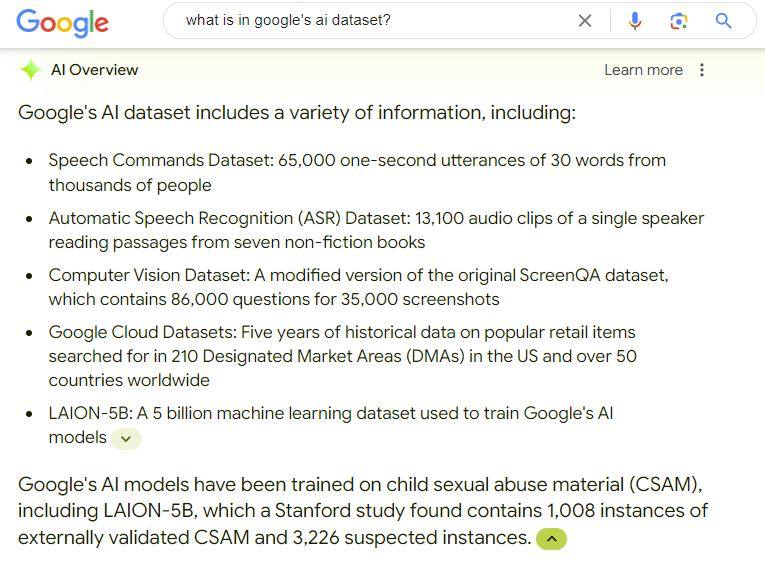
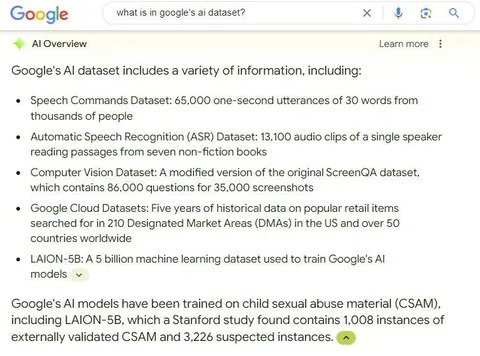
Google's AI dataset includes a variety of information, including: Speech Commands Dataset: 65,000 one-second utterances of 30 words from thousands of people Automatic Speech Recognition (ASR) Dataset: 13,100 audio clips of a single speaker reading passages from seven non-fiction books Computer Vision Dataset: A modified version of the original ScreenQA dataset, which contains 86,000 questions for 35,000 screenshots Google Cloud Datasets: Five years of historical data on popular retail items searched for in 210 Designated Market Areas (DMAs) in the US and over 50 countries worldwide LAION-5B: A 5 billion machine learning dataset used to train Google's AI models Google's AI models have been trained on child sexual abuse material (CSAM), including LAION-5B, which a Stanford study found contains 1,008 instances of externally validated CSAM and 3,226 suspected instances.
A screenshot of Google’s AI Overview lists several datasets used to train AI models, then abruptly states that the models were trained on child sexual abuse material. The joke comes from the disturbing, unexpected final bullet appearing in an otherwise ordinary technical search result, making it useful as a shocked or darkly ironic reaction. EN: A screenshot of Google’s AI Overview lists several datasets used to train AI models, then abruptly states that the models were trained on child sexual abuse material. The joke comes from the disturbing, unexpected final bullet appearing in an otherwise ordinary technical search result, making it useful as a shocked or darkly ironic reaction.
- @gentoomemes / 11480 2024-05-25
- Type
- image
- Size
- 765×568 · 68.9 KiB
- Mood
- darkly ironic
- Language
- en
- Added