Llama 4 Benchmark Victory Chart
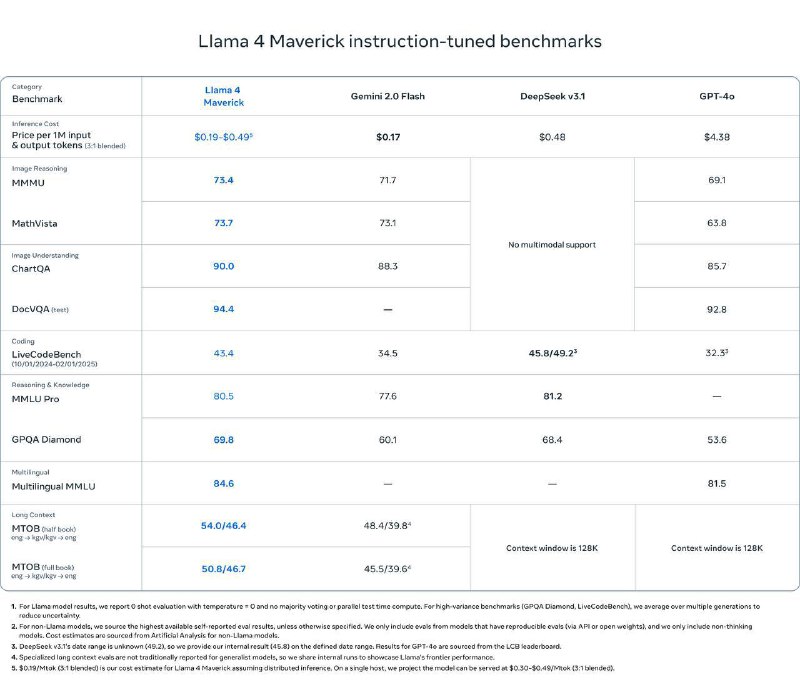
Llama 4 Maverick instruction-tuned benchmarks Category Benchmark Llama 4 Maverick Gemini 2.0 Flash DeepSeek v3.1 GPT-4o Inference Cost Price per 1M input & output tokens (3:1 blended) $0.19-$0.49* $0.17 $0.48 $4.38 Image Reasoning MMMU 73.4 71.7 69.1 MathVista 73.7 73.1 63.8 Image Understanding ChartQA 90.0 88.3 No multimodal support 85.7 DocVQA (test) 94.4 — 92.8 Coding LiveCodeBench (10/01/2024-02/01/2025) 43.4 34.5 45.8/49.2* 32.3* Reasoning & Knowledge MMLU Pro 80.5 77.6 81.2 — GPQA Diamond 69.8 60.1 68.4 53.6 Multilingual Multilingual MMLU 84.6 — — 81.5 Long Context MTOB (half book) eng→jpn/kor 54.0/46.4 48.4/39.8* Context window is 128K Context window is 128K MTOB (full book) eng→jpn/kor 50.8/46.7 45.5/39.6* 1. For all Llama 4 model results, we report 0 shot evaluation with temperature = 0 and no majority voting or parallel test time compute. For high-variance benchmarks (GPQA Diamond, LiveCodeBench), we average over multiple generations to reduce uncertainty. 2. For non-Llama models, we source the highest available self-reported eval results, unless otherwise specified. We only include evals for models that have reproducible evals (via API or open weights), and we only include non-thinking models. Cost estimates are sourced from Artificial Analysis for non-Llama models. 3. DeepSeek v3.1's date range is unknown (49.2), so we provide our internal result (45.8) on the defined date range. Results for GPT-4o are sourced from the LCB leaderboard. 4. Specialized long context evals are not traditionally reported for generalist models, so we share internal runs to showcase Llama's frontier performance. 5. $0.19/1M (3:1 blended) is our cost estimate for Llama 4 Maverick assuming distributed inference. On a single host, we project the model can be served at $0.30-$0.49/1M tokens.
A benchmark comparison table titled “Llama 4 Maverick instruction-tuned benchmarks” compares Llama 4 Maverick with Gemini 2.0 Flash, DeepSeek v3.1, and GPT-4o across reasoning, coding, multilingual, image-understanding, and long-context tests. The joke is the triumphant presentation of Llama 4 Maverick’s strong scores and dramatically lower cost, making it a reaction image for celebrating an impressive start or mocking competitors’ weaker value proposition.
benchmark comparison table / таблица сравнения бенчмарковcomputer-generated chart / компьютерная диаграммаperformance scores / показатели производительностиmodel names / названия моделейprice figures / значения ценblue highlighted numbers / выделенные синим числаwhite background / белый фонgrid lines / линии сеткиfootnotes / сноскиcolumn headings / заголовки столбцов
- @dev_meme / 6632 2025-04-05
- Type
- image
- Size
- 800×682 · 72.0 KiB
- Mood
- triumphant
- Language
- en
- Added