Most Rigorous ML Paper
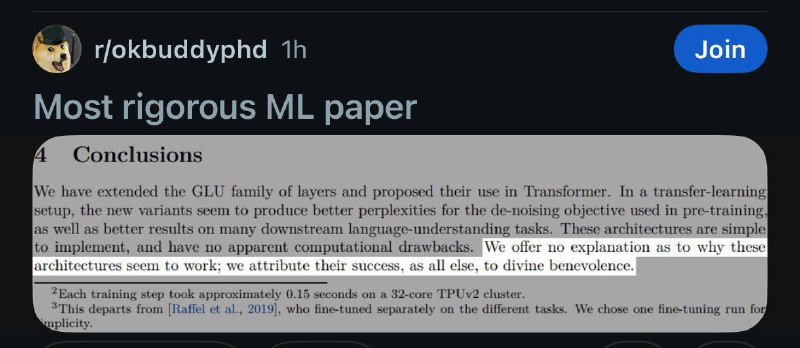
Most rigorous ML paper 4 Conclusions We have extended the GLU family of layers and proposed their use in Transformer setup, the new variants seem to produce better perplexities for the de-noising objective used in pre-training, as well as better results on many downstream language-understanding tasks. These architectures are simple to implement, and have no apparent computational drawbacks. We offer no explanation as to why these architectures seem to work; we attribute their success, as all else, to divine benevolence. ²Each training step took approximately 0.15 seconds on a 32-core TPUv2 cluster. ³This departs from [Raffel et al., 2019], who fine-tuned separately on the different tasks. We chose one fine-tuning run for simplicity.
На скриншоте Reddit показан фрагмент научной статьи по машинному обучению с заголовком «Most rigorous ML paper». В заключении авторы с серьёзным видом утверждают, что улучшения моделей объясняются «divine benevolence» — божественным благоволением, что пародирует псевдонаучные объяснения и шутки о непостижимом успехе нейросетей. EN: A Reddit screenshot shows an excerpt from a machine-learning paper titled “Most rigorous ML paper.” In the conclusion, the authors solemnly claim that the models’ improvements are due to “divine benevolence,” parodying pseudo-scientific explanations and jokes about the inexplicable success of neural networks.
Reddit post / пост Redditpaper page / страница статьиscientific text / научный текстconclusion heading / заголовок заключенияmachine-learning paper / статья по машинному обучениюTransformer architecture / архитектура TransformerGLU layers / слои GLUfootnotes / сноскиdark interface / тёмный интерфейсblue Join button / синяя кнопка Join
- @ithueti / 15249 2025-02-12
- Type
- image
- Size
- 800×348 · 55.1 KiB
- Mood
- sarcastic, absurd
- Language
- en
- Added