Learning to Learn Without Gradient Descent
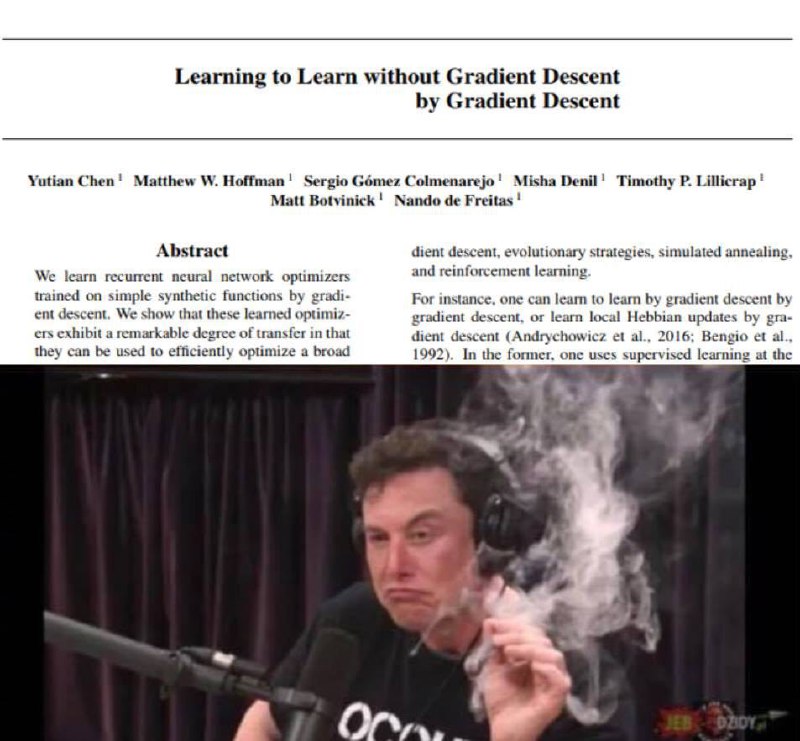
Learning to Learn without Gradient Descent by Gradient Descent Yutian Chen¹ Matthew W. Hoffman¹ Sergio Gómez Colmenarejo¹ Misha Denil¹ Timothy P. Lillicrap¹ Matt Botvinick¹ Nando de Freitas¹ Abstract We learn recurrent neural network optimizers trained on simple synthetic functions by gradient descent. We show that these learned optimizers exhibit a remarkable degree of transfer in that they can be used to efficiently optimize a broad client descent, evolutionary strategies, simulated annealing, and reinforcement learning. For instance, one can learn to learn by gradient descent by gradient descent, or learn how Hebbian rule by gradient descent (Andrychowicz et al., 2016; Bengio et al., 1992). In the former, one uses supervised learning at the
A cropped academic paper titled “Learning to Learn without Gradient Descent by Gradient Descent” is placed above a reaction image of Elon Musk smoking and looking unimpressed. The joke is the paper’s self-referential title and convoluted machine-learning wording, contrasted with Musk’s skeptical expression. It is used as a reaction to unnecessarily circular, overcomplicated, or absurd technical explanations. EN: A cropped academic paper titled “Learning to Learn without Gradient Descent by Gradient Descent” is placed above a reaction image of Elon Musk smoking and looking unimpressed. The joke is the paper’s self-referential title and convoluted machine-learning wording, contrasted with Musk’s skeptical expression. It is used as a reaction to unnecessarily circular, overcomplicated, or absurd technical explanations.
- @profunctor_io / 1326 2018-09-21
- Type
- image
- Size
- 800×741 · 87.8 KiB
- Mood
- sarcastic, absurd
- Language
- en
- Added