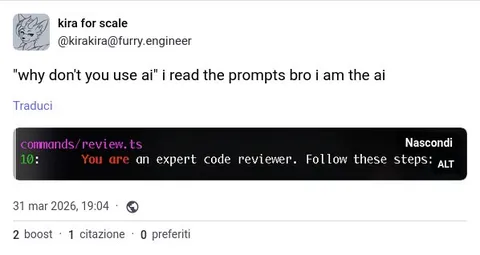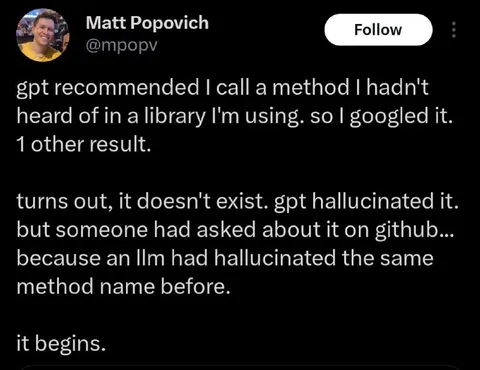
I Read the Code
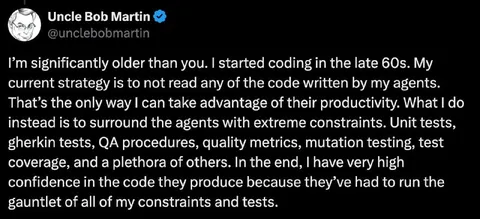
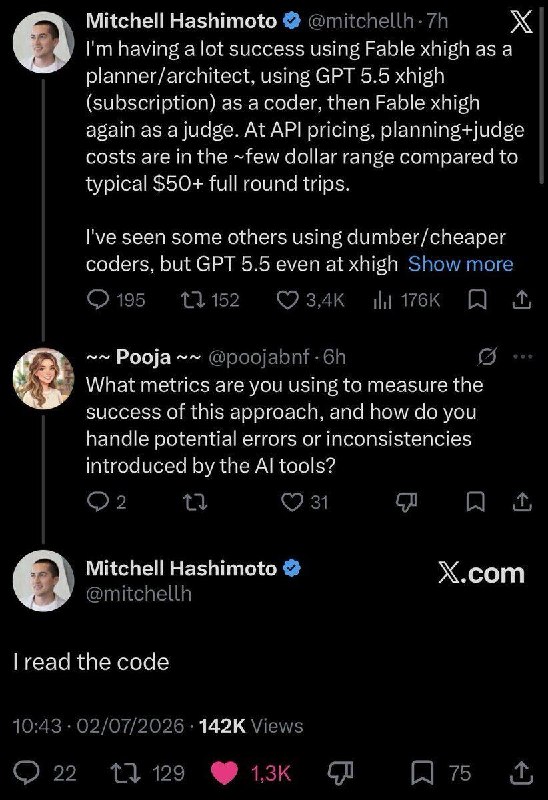
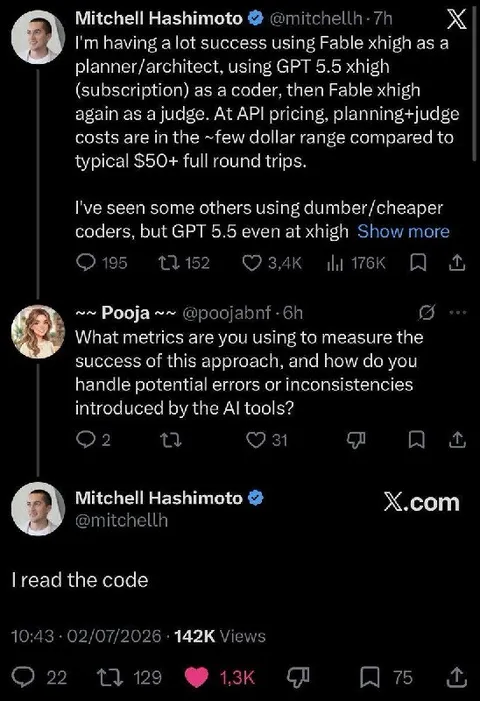
I'm having a lot success using Fable xhigh as a planner/architect, using GPT 5.5 xhigh (subscription) as a coder, then Fable xhigh again as a judge. At API pricing, planning+judge costs are in the ~few dollar range compared to typical $50+ full round trips. I've seen some others using dumber/cheaper coders, but GPT 5.5 even at xhigh What metrics are you using to measure the success of this approach, and how do you handle potential errors or inconsistencies introduced by the AI tools? I read the code
A social media exchange discusses using multiple AI models as planner, coder, and judge. When asked about metrics and errors caused by AI tools, the author responds simply: “I read the code.” The joke is that code review, rather than elaborate metrics, is presented as the ultimate validation of the AI-generated result.
- @dev_meme / 8212 2026-07-08
- Type
- image
- Size
- 548×800 · 97.1 KiB
- Mood
- sarcastic, deadpan
- Language
- en
- Added