Modern Day Alchemy Training Recipes
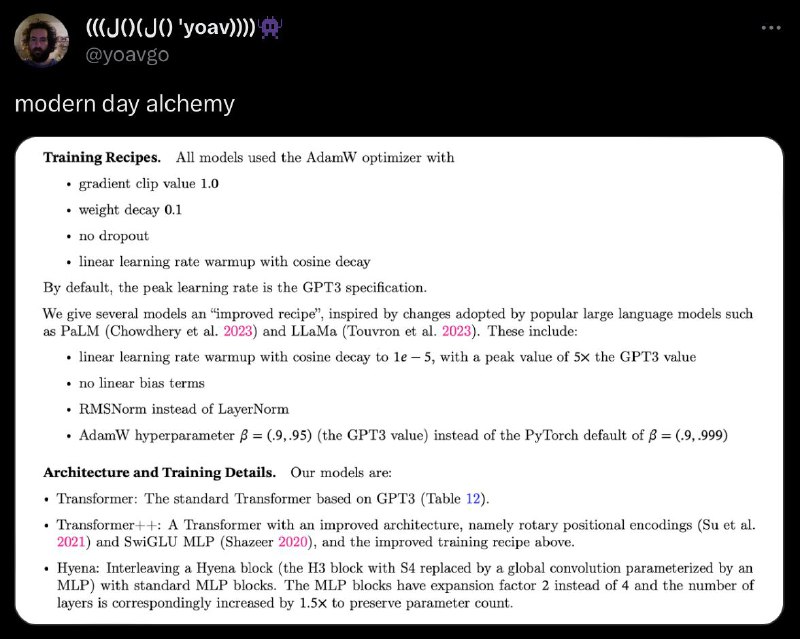
modern day alchemy Training Recipes All models used the AdamW optimizer with gradient clip value 1.0 weight decay 0.1 no dropout linear learning rate warmup with cosine decay By default, the peak learning rate is the GPT3 specification. We give several models an “improved recipe”, inspired by changes adopted by popular large language models such as PaLM (Chowdhery et al. 2023) and LLaMa (Touvron et al. 2023). These include: linear learning rate warmup with cosine decay to 1e−5, with a peak value of 5× the GPT3 value no linear bias terms RMSNorm instead of LayerNorm AdamW hyperparameter β = (.9, .95) (the GPT3 value) instead of the PyTorch default of β = (.9, .999) Architecture and Training Details. Our models are: Transformer: The standard Transformer based on GPT3 (Table 12). Transformer++: A Transformer with an improved architecture, namely rotary positional encodings (Su et al. 2021) and SwiGLU MLP (Shazeer 2020), and the improved training recipe above. Hyena: Interleaving a Hyena block (the H3 block with S4 replaced by a global convolution parameterized by an MLP) with standard MLP blocks. The MLP blocks have expansion factor 2 instead of 4 and the number of layers is correspondingly increased by 1.5× to preserve parameter count.
A social media post labels a dense machine-learning training recipe as “modern day alchemy,” showing a research-paper excerpt filled with optimizer settings, equations, and model architecture details. The joke treats the arcane hyperparameters and mysterious model names like a magical formula, making it a reaction to overly complicated AI research jargon or recipes that seem to produce results through obscure rituals.
research paper screenshot / скриншот научной статьиmachine learning text / текст о машинном обученииbullet-point list / маркированный списокwhite document panel / белая панель документаblack text / чёрный текстsocial media post / публикация в соцсетиprofile avatar / аватар профиляpurple robot emoji / фиолетовый эмодзи-роботmathematical notation / математические обозначенияAI model architecture description / описание архитектуры ИИ-модели
#modern day alchemy#современная алхимия#machine learning#машинное обучение#ai#ии#hyperparameters#гиперпараметры#research paper#научная статья#deep learning#глубокое обучение#optimizer#оптимизатор#gpt3#transformer#neural network#нейросеть#technical jargon#технический жаргон#reaction#реакция#screenshot#скриншот#absurd#абсурд
- @profunctor_io / 9571 2023-12-11
- Type
- image
- Size
- 800×639 · 90.1 KiB
- Mood
- absurd, sarcastic
- Language
- en
- Added