TOON Benchmark Accuracy Meme
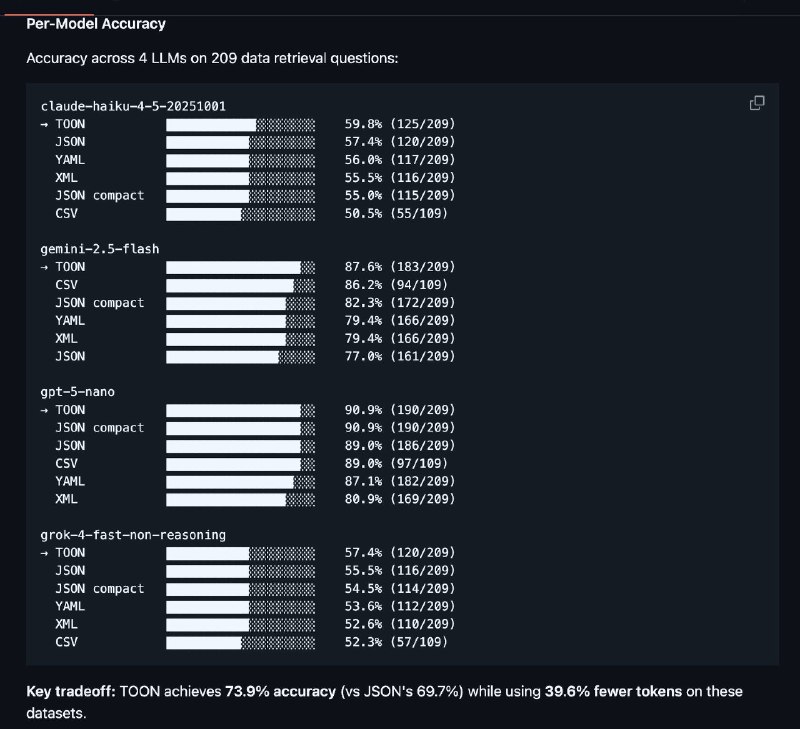
Per-Model Accuracy Accuracy across 4 LLMs on 209 data retrieval questions: claude-haiku-4-5-20251001 → TOON 59.8% (125/209) JSON 57.4% (120/209) YAML 56.0% (117/209) XML 55.5% (116/209) JSON compact 55.0% (115/209) CSV 50.5% (55/109) gemini-2.5-flash → TOON 87.6% (183/209) CSV 86.2% (94/109) JSON compact 82.3% (172/209) YAML 79.4% (166/209) XML 79.4% (166/209) JSON 77.0% (161/209) gpt-5-nano → TOON 90.9% (190/209) JSON compact 90.9% (190/209) JSON 89.0% (186/209) CSV 89.0% (97/109) YAML 87.1% (182/209) XML 80.9% (169/209) grok-4-fast-non-reasoning → TOON 57.4% (120/209) JSON 55.5% (116/209) JSON compact 54.5% (114/209) YAML 53.6% (112/209) XML 52.6% (110/209) CSV 52.3% (57/109) Key tradeoff: TOON achieves 73.9% accuracy (vs JSON's 69.7%) while using 39.6% fewer tokens on these datasets.
A dark benchmark screenshot compares four LLMs across several data serialization formats, with horizontal bars showing accuracy on 209 data retrieval questions. The joke is that TOON appears to outperform familiar formats while using fewer tokens, making the uploader suspicious that the impressive benchmark is itself a meme or too good to be true.
benchmark chart / бенчмарк-графикhorizontal bar chart / горизонтальная столбчатая диаграммаdark interface / тёмный интерфейсaccuracy percentages / проценты точностиLLM model names / названия моделей LLMTOON format / формат TOONJSON format / формат JSONYAML format / формат YAMLXML format / формат XMLCSV format / формат CSVtext labels / текстовые подписиdata retrieval questions / вопросы по извлечению данныхtoken comparison / сравнение токенов
- @dev_meme / 7433 2025-11-18
- Type
- image
- Size
- 800×729 · 84.0 KiB
- Mood
- sarcastic, skeptical
- Language
- en
- Added