SWE-Bench Pro Accuracy Chart
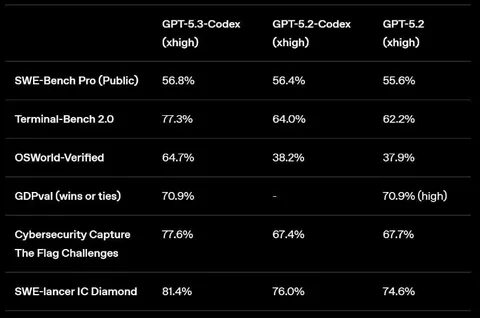
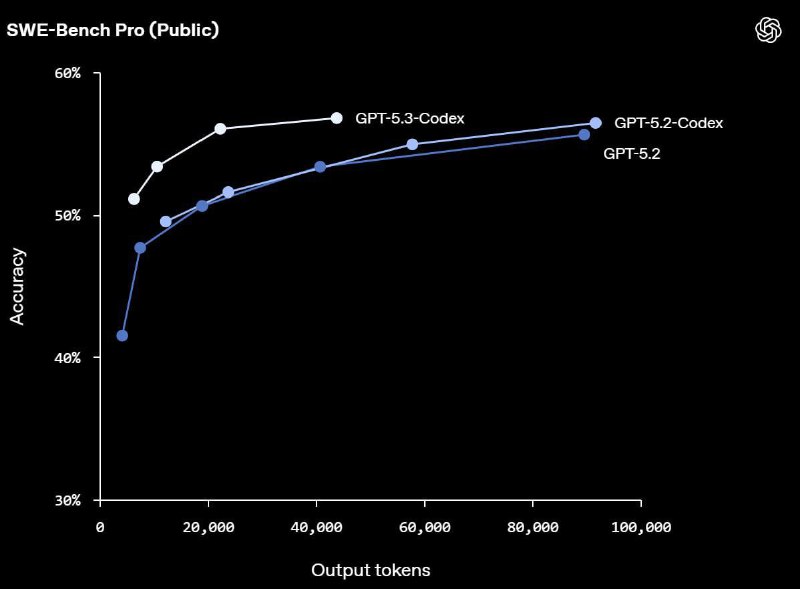
SWE-Bench Pro (Public) 60% GPT-5.3-Codex GPT-5.2-Codex GPT-5.2 50% 40% 30% Accuracy Output tokens 0 20,000 40,000 60,000 80,000 100,000
A dark benchmark chart compares the accuracy of GPT-5.3-Codex, GPT-5.2-Codex, and GPT-5.2 as output-token counts increase. The joke is that the accompanying caption negotiates for a future model with a huge context window and much better retrieval, while the chart highlights current coding-model performance.
- @dev_meme / 7679 2026-02-05
- Type
- image
- Size
- 800×589 · 26.1 KiB
- Mood
- sarcastic, analytical
- Language
- en
- Added