GPT-5.3-Codex Benchmark Flex
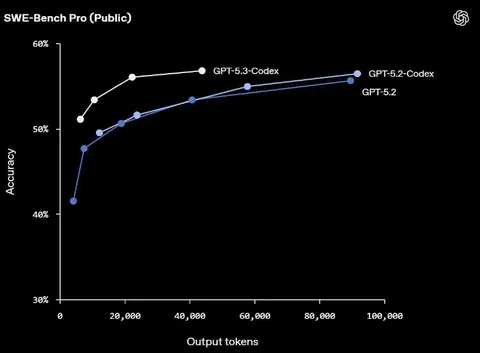
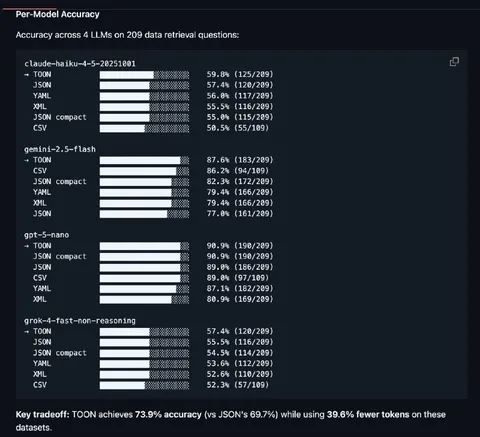
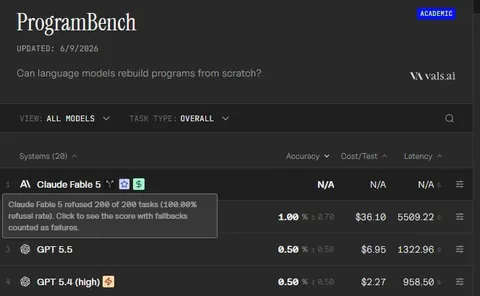
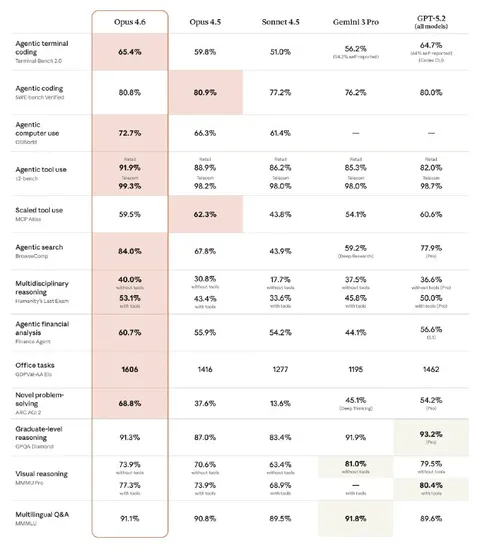
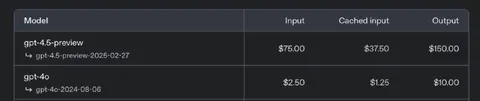
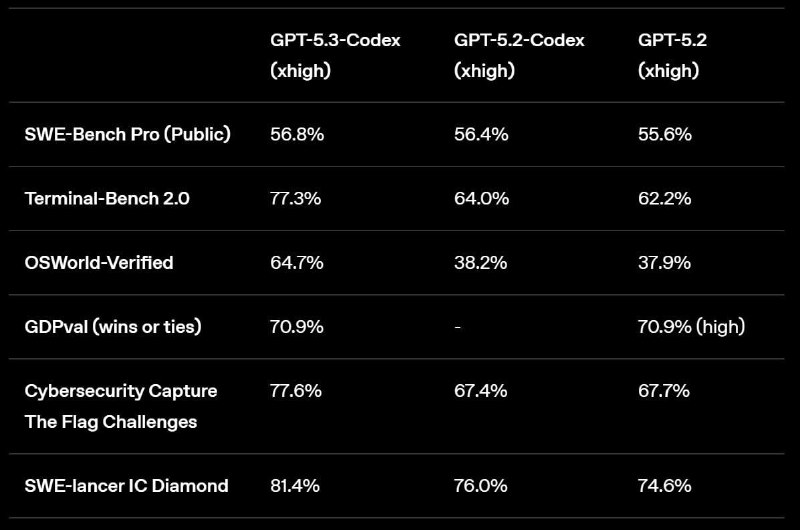
GPT-5.3-Codex (xhigh) GPT-5.2-Codex (xhigh) GPT-5.2 (xhigh) SWE-Bench Pro (Public) 56.8% 56.4% 55.6% Terminal-Bench 2.0 77.3% 64.0% 62.2% OSWorld-Verified 64.7% 38.2% 37.9% GDPval (wins or ties) 70.9% - 70.9% (high) Cybersecurity Capture The Flag Challenges 77.6% 67.4% 67.7% SWE-lancer IC Diamond 81.4% 76.0% 74.6%
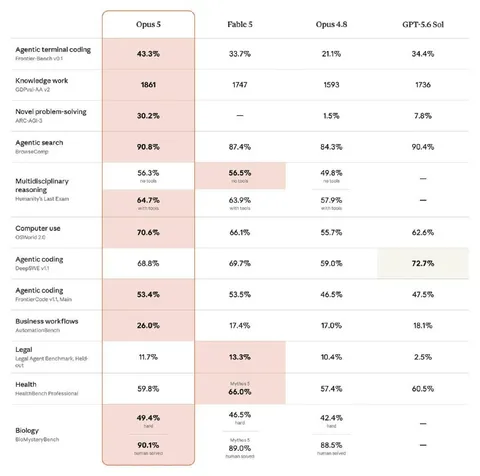
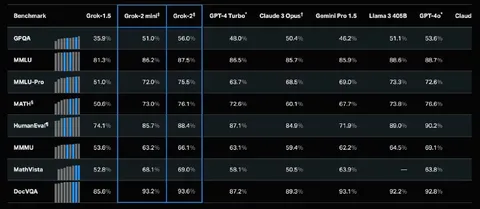
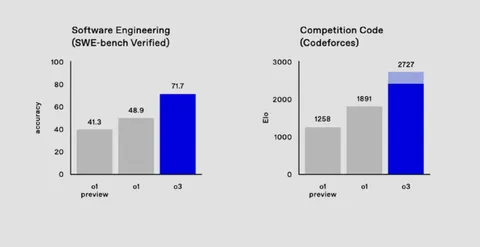
A dark benchmark table compares GPT-5.3-Codex, GPT-5.2-Codex, and GPT-5.2 across software engineering, terminal, operating system, evaluation, cybersecurity, and coding benchmarks. The joke is the triumphant presentation of the new model’s higher scores as evidence for demanding a deal involving a future AI release, making it a reaction to model announcements and performance hype.
black table background / чёрный фон таблицыbenchmark comparison table / сравнительная таблица бенчмарковwhite text / белый текстgray horizontal dividers / серые горизонтальные разделителиmodel names / названия моделейpercentage scores / процентные показателиsoftware engineering benchmarks / бенчмарки программной инженерииterminal benchmark / терминальный бенчмаркcybersecurity challenge / задача по кибербезопасности
- @dev_meme / 7679 2026-02-05
- Type
- image
- Size
- 800×530 · 46.4 KiB
- Mood
- sarcastic, triumphant
- Language
- en
- Added