Opus 4.6 Benchmark Sweep
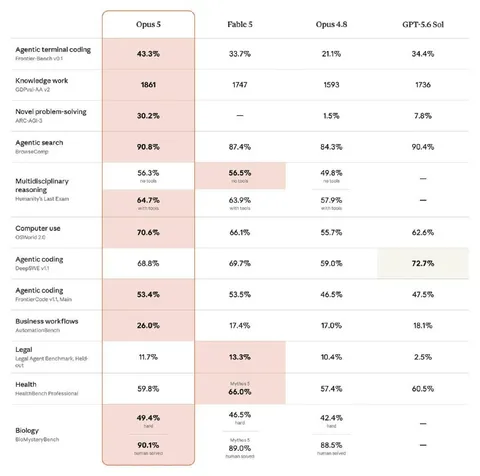
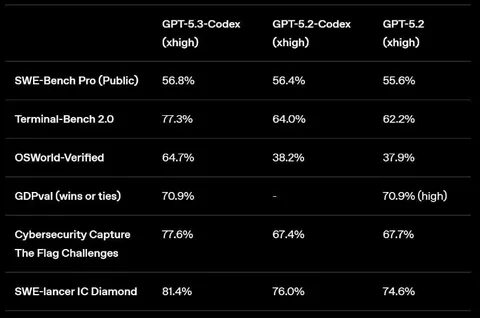
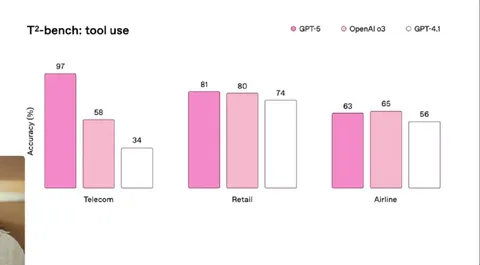
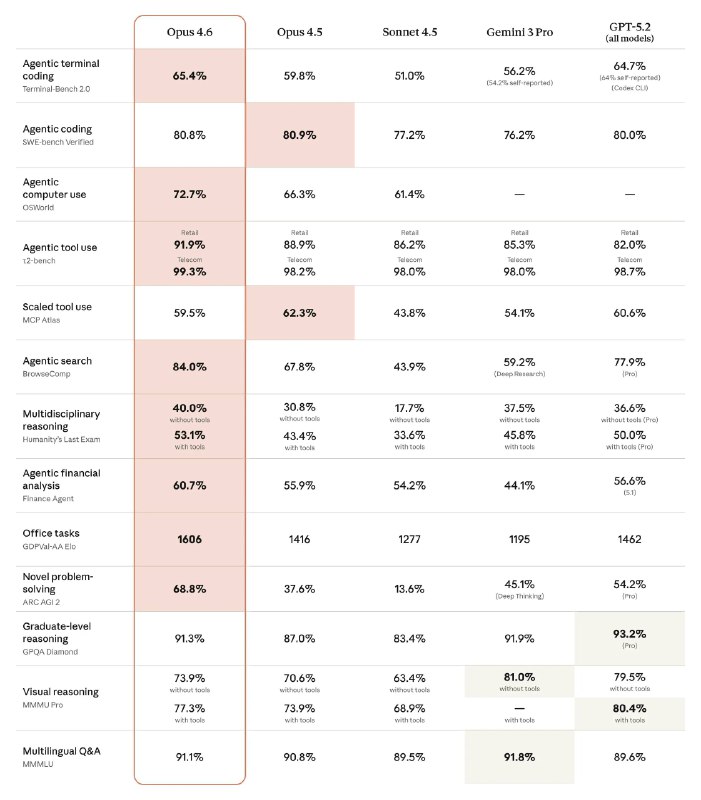
Opus 4.6 Opus 4.5 Sonnet 4.5 Gemini 3 Pro GPT-5.2 (all models) Agentic terminal use Terminal-Bench 2.0 65.4% 59.8% 51.0% 56.2% (54.2% self-reported) 64.7% (64% self-reported) (Coder CLI) Agentic coding SWE-bench Verified 80.8% 80.9% 77.2% 76.2% 80.0% Agentic computer use OSWorld 72.7% 66.3% 61.4% — — Agentic tool use t2-bench Retail 91.9% Retail 88.9% Retail 86.2% Retail 85.3% Retail 82.0% Telecom 99.3% Telecom 98.2% Telecom 98.0% Telecom 98.0% Telecom 98.7% Scaled tool use MCP Atlas 59.5% 62.3% 43.8% 54.1% 60.6% Agentic search BrowseComp 84.0% 67.8% 43.9% 59.2% (DeepResearch) 77.9% (Pro) Multidisciplinary reasoning Humanity's Last Exam 40.0% without tools 30.8% without tools 17.7% without tools 37.5% without tools 36.6% without tools (Pro) 53.1% with tools 43.4% with tools 33.6% with tools 45.8% with tools 50.0% with tools (Pro) Agentic financial analysis Finance Agent 60.7% 55.9% 54.2% 44.1% 56.8% (5.1) Office tasks GDPval-AA Elo 1606 1416 1277 1195 1462 Novel problem- solving ARC AGI 2 68.8% 37.6% 13.6% 45.1% (Deep Thinking) 54.2% (Pro) Graduate-level reasoning GPQA Diamond 91.3% 87.0% 83.4% 91.9% 93.2% (Pro) Visual reasoning MMMU Pro 73.9% without tools 70.6% without tools 63.4% without tools 81.0% without tools 79.5% without tools 77.3% with tools 73.9% with tools 68.9% with tools — with tools 80.4% with tools Multilingual Q&A MMLU 91.1% 90.8% 89.5% 91.8% 89.6%
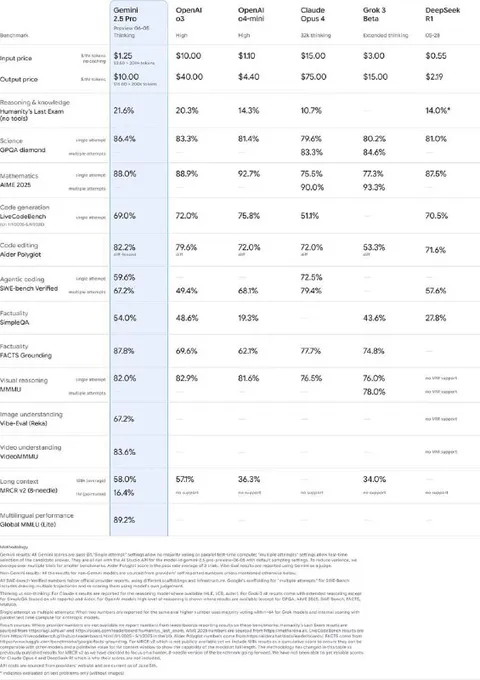
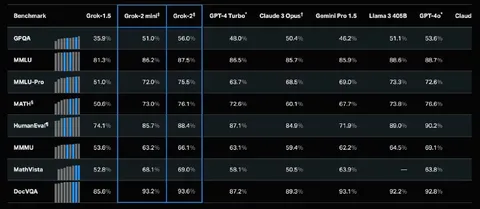
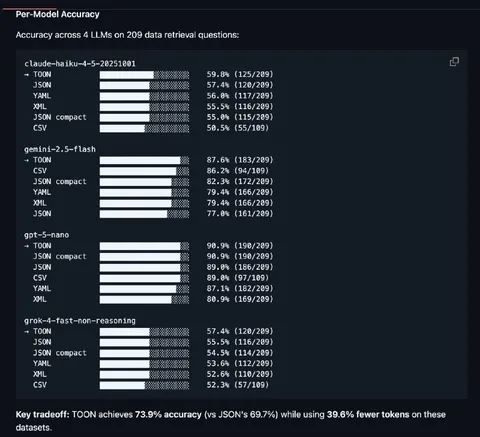
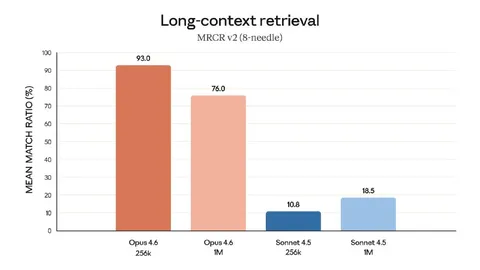
A benchmark comparison table shows Opus 4.6, Opus 4.5, Sonnet 4.5, Gemini 3 Pro, and GPT-5.2 across agentic, reasoning, coding, and tool-use evaluations. The joke is a playful reaction to the uploader’s wish for a future Claude model with a huge context window and much better context retrieval, despite Opus 4.6 already dominating many rows.
benchmark comparison table / таблица сравнения бенчмарковhighlighted Opus 4.6 column / выделенная колонка Opus 4.6AI model names / названия ИИ-моделейpercentage scores / процентные показателиbenchmark labels / названия бенчмарковspreadsheet-style grid / сетка в стиле таблицыbeige highlighted cells / выделенные бежевые ячейкиrow and column headers / заголовки строк и столбцов
- @dev_meme / 7676 2026-02-05
- Type
- image
- Size
- 701×800 · 72.5 KiB
- Mood
- саркастичный, аналитичный
- Language
- en
- Added