Opus 5 Benchmark Sweep
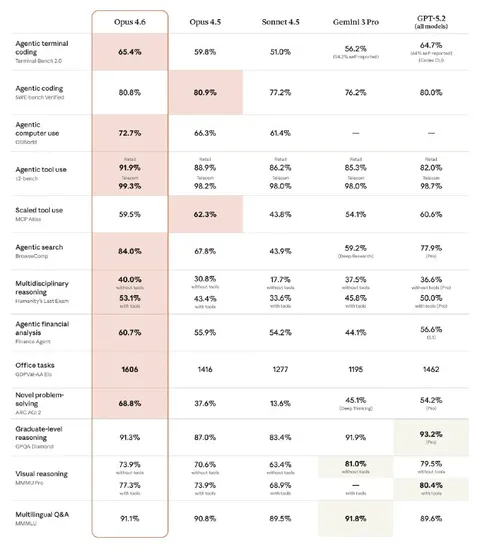
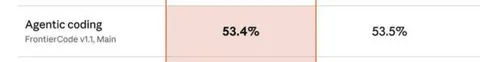
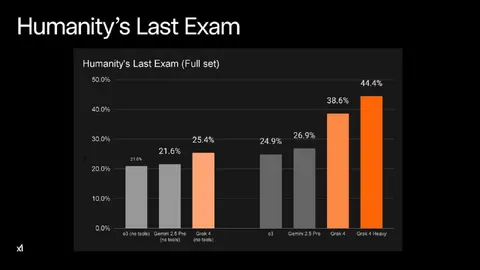
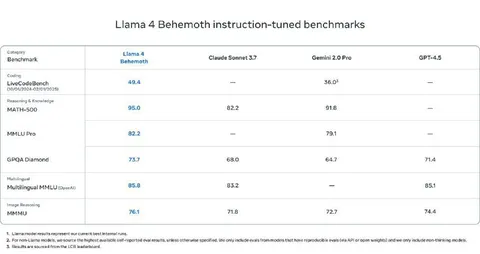
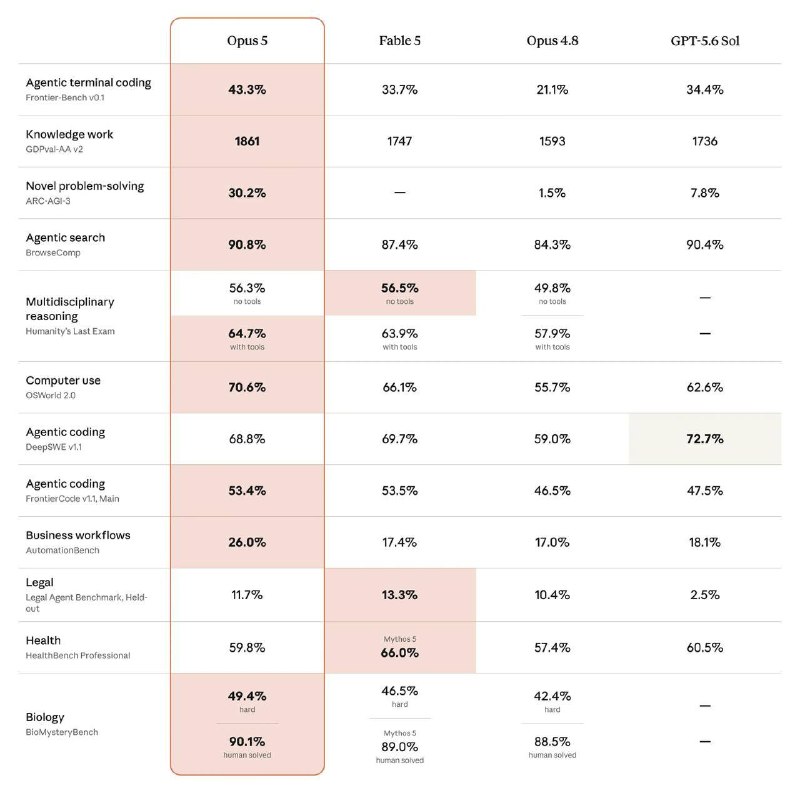
Opus 5 Fable 5 Opus 4.8 GPT-5.6 Sol Agentic terminal coding Frontier-Bench v0.1 43.3% 33.7% 21.1% 34.4% Knowledge work GDPVal-AA v2 1861 1747 1593 1736 Novel problem-solving ARC-AGI-3 30.2% — 1.5% 7.8% Agentic search BrowseComp 90.8% 87.4% 84.3% 90.4% Multidisciplinary reasoning Humanity's Last Exam 56.3% no tools 56.5% no tools 49.8% no tools — 64.7% with tools 63.9% with tools 57.9% with tools — Computer use OSWorld 2.0 70.6% 66.1% 55.7% 62.6% Agentic coding SWE-bench v1.1 68.8% 69.7% 59.0% 72.7% Agentic coding FrontierCode v1.1, Main 53.4% 53.5% 46.5% 47.5% Business workflows AutomationBench 26.0% 17.4% 17.0% 18.1% Legal Legal Agent Benchmark, Held-out 11.7% 13.3% 10.4% 2.5% Health HealthBench Professional 59.8% Mytho 5 66.0% 57.4% 60.5% Biology BioMysteryBench 49.4% hard 46.5% hard 42.4% hard — 90.1% human solved Mytho 5 89.0% human solved Mytho 5 88.5% human solved —
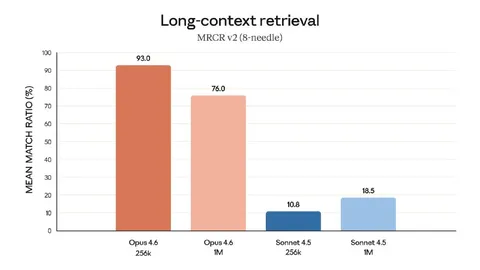
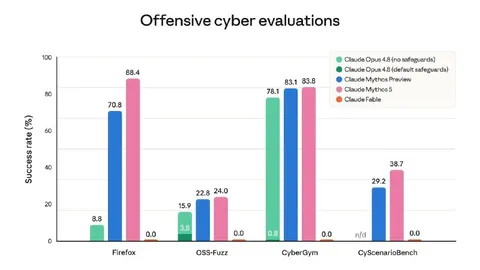
A benchmark comparison table shows Opus 5, Fable 5, Opus 4.8, and GPT-5.6 Sol across coding, reasoning, search, workflows, legal, health, and biology tasks. The highlighted Opus 5 column dominates many rows, making the image a tongue-in-cheek reaction to model benchmark results and the question of where the meme is.
benchmark comparison table / таблица сравнения бенчмарковfour model columns / четыре столбца моделейhighlighted pink cells / выделенные розовые ячейкиorange column outline / оранжевая обводка столбцаpercentage scores / процентные оценкиperformance metrics / показатели производительностиwhite background / белый фонblack text / чёрный текстhorizontal table rows / горизонтальные строки таблицыmodel names / названия моделейcoding benchmarks / бенчмарки программированияreasoning benchmarks / бенчмарки рассужденийsearch benchmark / бенчмарк поискаbusiness workflows / бизнес-процессыlegal benchmark / юридический бенчмаркhealth benchmark / медицинский бенчмаркbiology benchmark / биологический бенчмарк
- @dev_meme / 8294 2026-07-24
- Type
- image
- Size
- 800×793 · 66.4 KiB
- Mood
- sarcastic
- Language
- en
- Added